cap-evolve
Optimize any AI agent's skills, tools/MCP and prompts against your own evals.
🫐 Open source · Apache-2.0
Skillberry provides a framework for enterprise-ready agentic capabilities — skills, tools, and prompts. It emphasizes the usage of approved, determinism-rich capabilities at runtime to minimize reliance on LLMs and enhance trustworthiness.
Skillberry provides scalable skills, tools and MCP runtime management and automation.
Skillberry performs iterative optimization to accelerate generation, testing, and refinement of agentic capabilities.
Skillberry reliably simulates and benchmarks real-world agentic interactions, built from real test cases.
Optimize any AI agent's skills, tools/MCP and prompts against your own evals.
The open-source control plane for agent skills, tools and snippets.
Simulate MCP tools and skills — no backends, credentials or side effects.
Skill-based test suite generator for agentic systems.
One client for many LLM providers — tool calls, structured outputs, retries.
A proxy-agent that connects your agents to Skillberry skills.
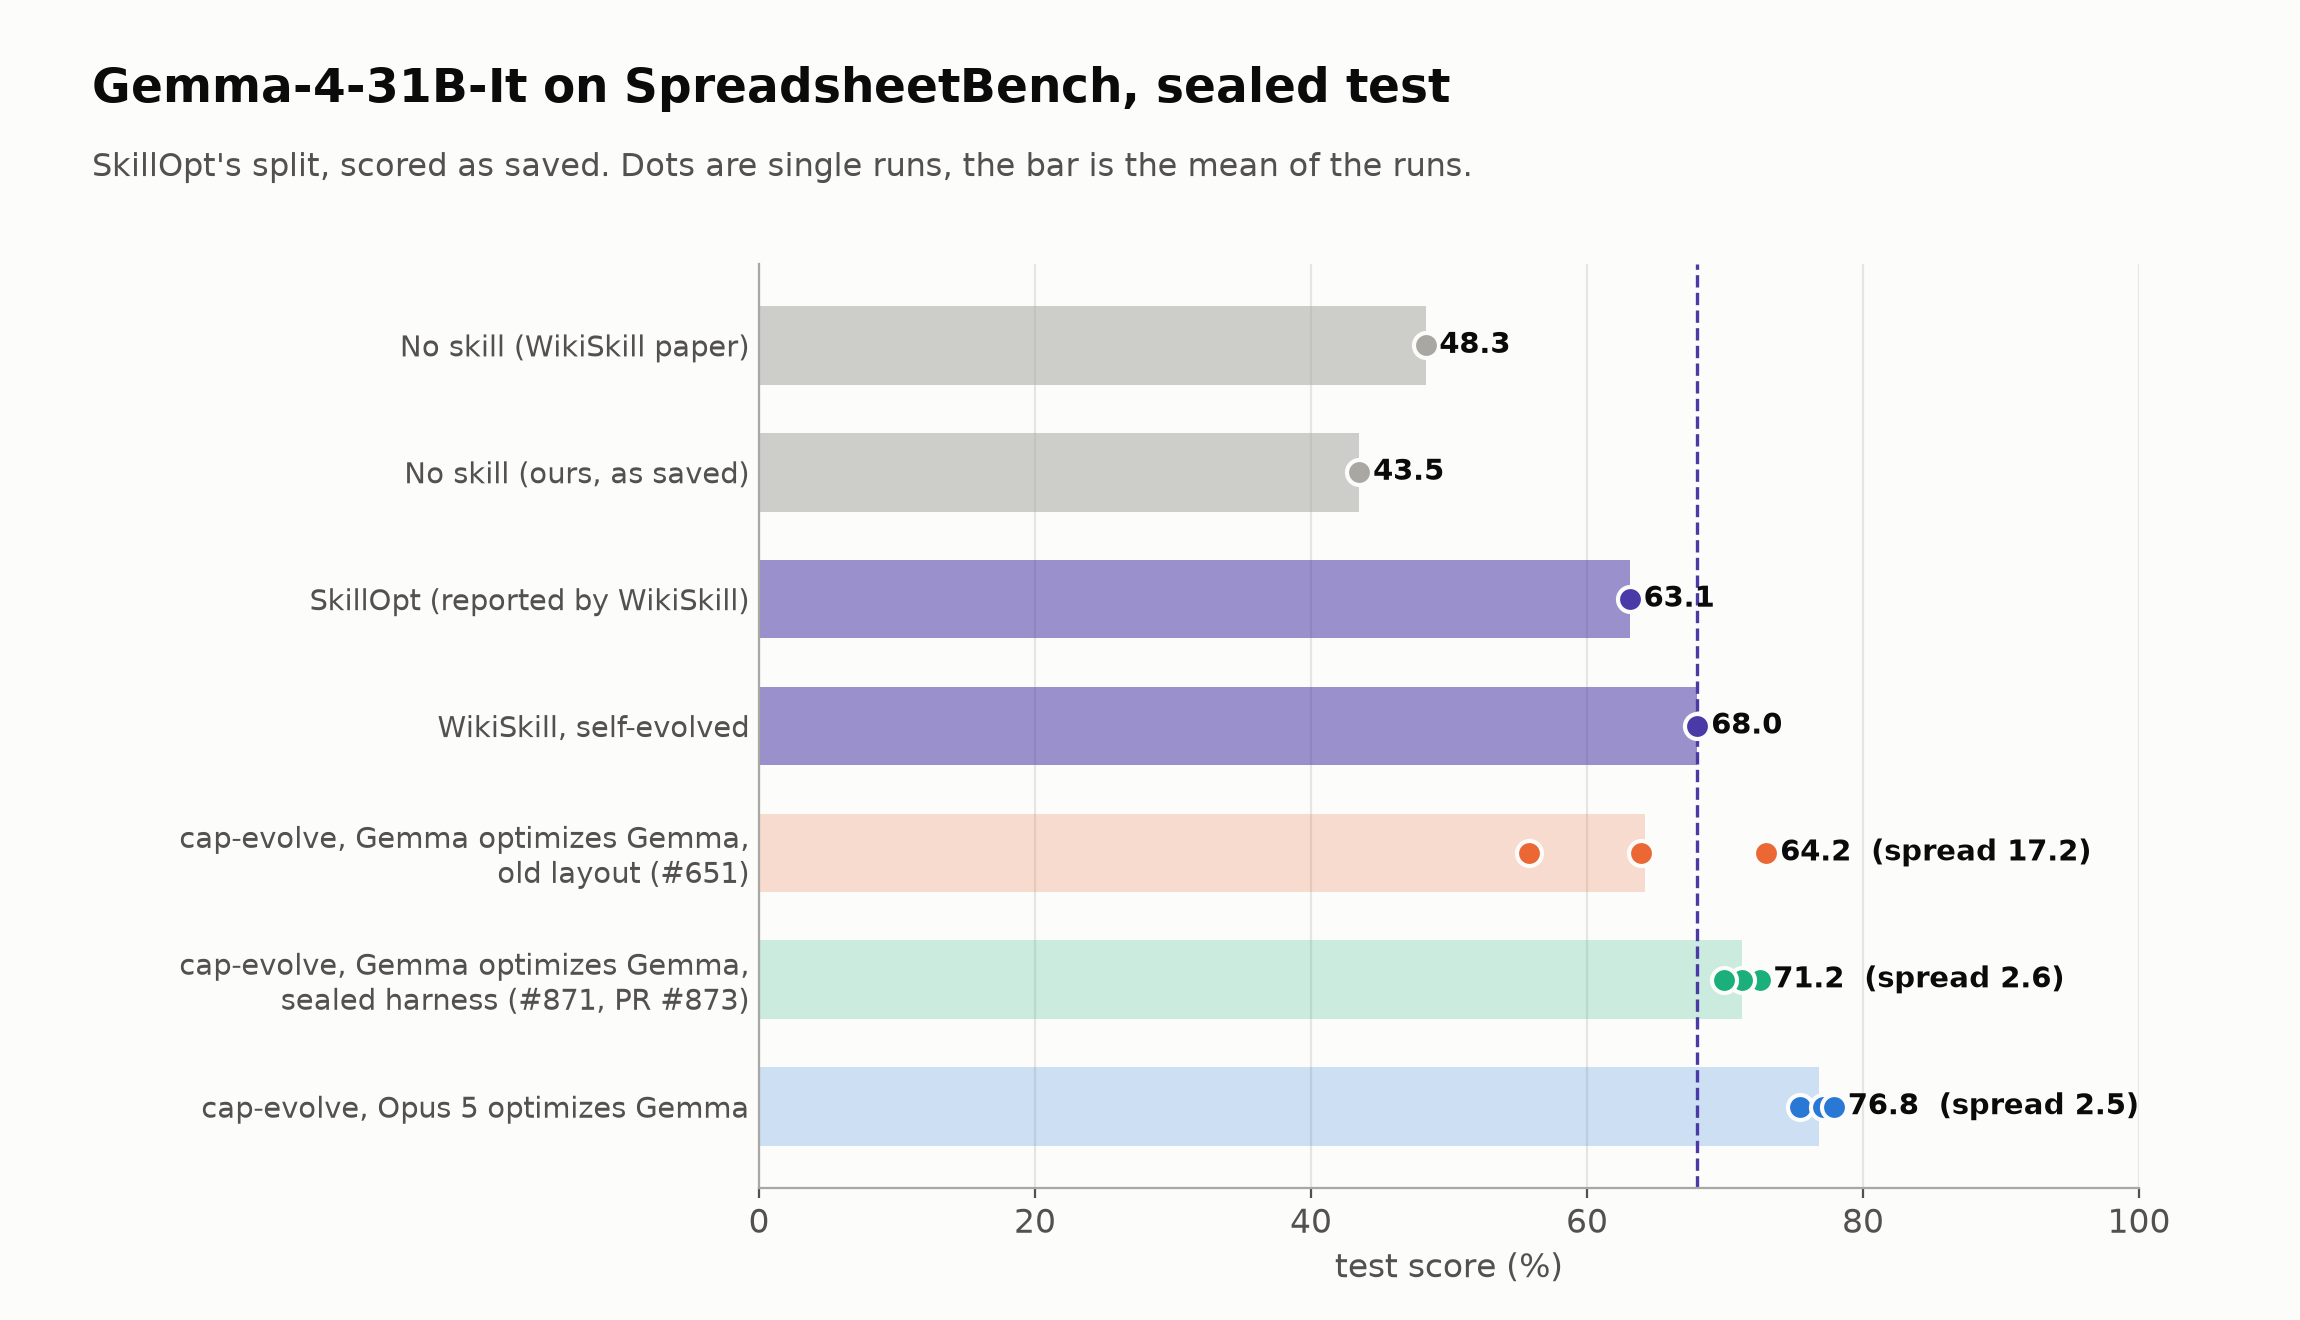
With its weights unchanged, Gemma-4-31B goes from 43.5% to 76.8% on held-out SpreadsheetBench tasks once cap-evolve rewrites its instructions. That is 8.8 points above the best published result. The post covers the method and how the comparison was kept fair.
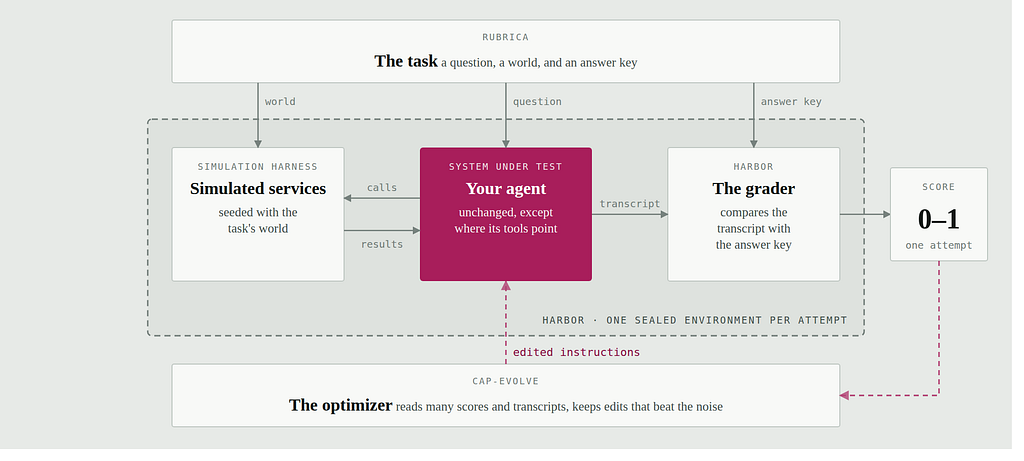
Tests a model writes from a single prompt are a vibe check with checkmarks. This post builds a lab for agents (Simulation Harness for the world, Rubrica for trusted tasks, cap-evolve for the fixes) and uses it to find real bugs in Red Hat's PARSEC.
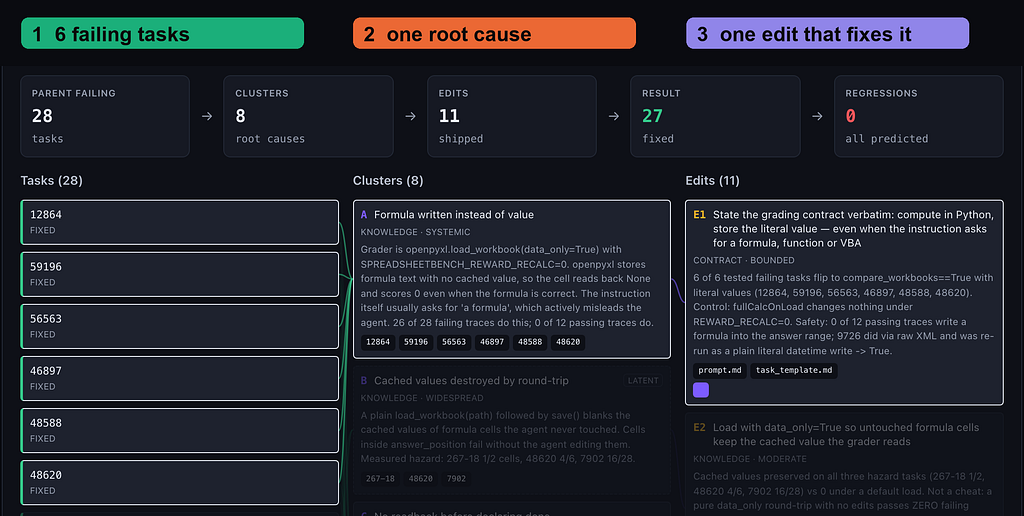
A higher score doesn't tell you why. The new CapEvolve UI traces each failing task to its root cause, the edit that fixed it and the candidates the gate refused. In one run, a single prompt rule lifted held-out accuracy from 38.6% to 89.8%.
🤖📺 The bots are still in the editing room — no public videos yet.
Subscribe to @skillberry-ai to catch the first upload.